Run Zeng
 RIT Research Assistant
Hi! It's Run here! ツ
I am currently a third-year PhD student at RIT, advised by Prof. Dongfang Liu.
My research focuses on efficient LLMs across their full lifecycle, spanning training, adaptation, reasoning, and agentic systems.
Research Interests: LLMs GenAI Agentic AI LLMs Adaptation LLMs Training Reasoning RL
University email: rz4545@rit.edu (Preferred) / run@mail.rit.edu
Personal email: runjia@msn.com
Action required
Problem: The current root path of this site is "baseurl ("_config.yml.
Solution: Please set the
baseurl in _config.yml to "Publications
Two Actions from One State: Fork Futures Teach JEPA World Models to Compare
Yihao Wu, Runjia Zeng, Tongyan Wang, et al.
arXiv 2026
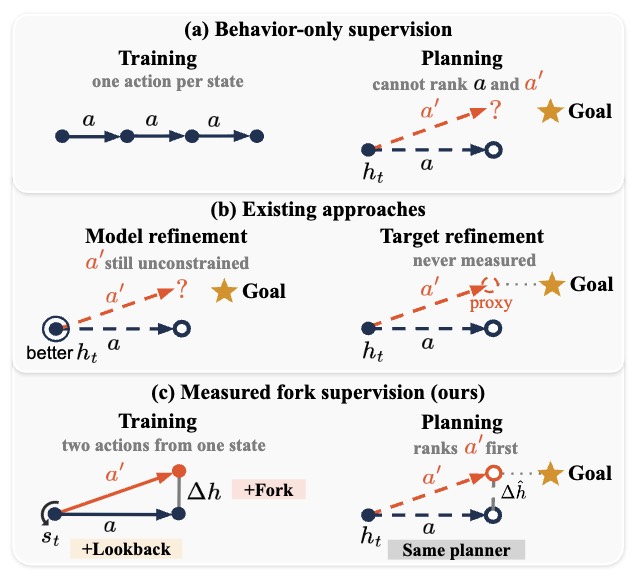
→ ExpandJEPA world models are trained to predict logged transitions but used to compare counterfactual actions from one state. The logged behavior data show one action per state, and under a local linear approximation we prove the action response is unidentified along any direction the policy never varies within a state. We therefore supplement behavior data with measured outcomes of alternative actions from the same state. Our fork futures execute two actions from one restored state, and their outcome difference cancels the state term, identifying the action response on the sampled span. The resulting model, Fork-JEPA, matches predicted to measured differences, anchors the logged successor with behavior prediction, and adds a lookback head that keeps the predecessor recoverable, all at training time, leaving planning unchanged. On three visual control tasks, behavior-only training leaves the predicted action effect no better than a constant guess. Fork-JEPA makes it readable and raises planning success by up to 14% over LeWM, its base model. Where the action response changes across hidden zones, it nearly doubles cross-zone success, and 1,024 fork pairs beat 1.2M extra behavior steps.
Two Actions from One State: Fork Futures Teach JEPA World Models to Compare
Yihao Wu, Runjia Zeng, Tongyan Wang, et al.
arXiv 2026
→ ExpandJEPA world models are trained to predict logged transitions but used to compare counterfactual actions from one state. The logged behavior data show one action per state, and under a local linear approximation we prove the action response is unidentified along any direction the policy never varies within a state. We therefore supplement behavior data with measured outcomes of alternative actions from the same state. Our fork futures execute two actions from one restored state, and their outcome difference cancels the state term, identifying the action response on the sampled span. The resulting model, Fork-JEPA, matches predicted to measured differences, anchors the logged successor with behavior prediction, and adds a lookback head that keeps the predecessor recoverable, all at training time, leaving planning unchanged. On three visual control tasks, behavior-only training leaves the predicted action effect no better than a constant guess. Fork-JEPA makes it readable and raises planning success by up to 14% over LeWM, its base model. Where the action response changes across hidden zones, it nearly doubles cross-zone success, and 1,024 fork pairs beat 1.2M extra behavior steps.
The Generative Crossroads: Diffusion or Autoregression for Language Modeling?
Xiang Zhang, Yiyang Liu, Runjia Zeng, et al.
EACL Findings Findings of the European Chapter of the Association for Computational Linguistics 2027
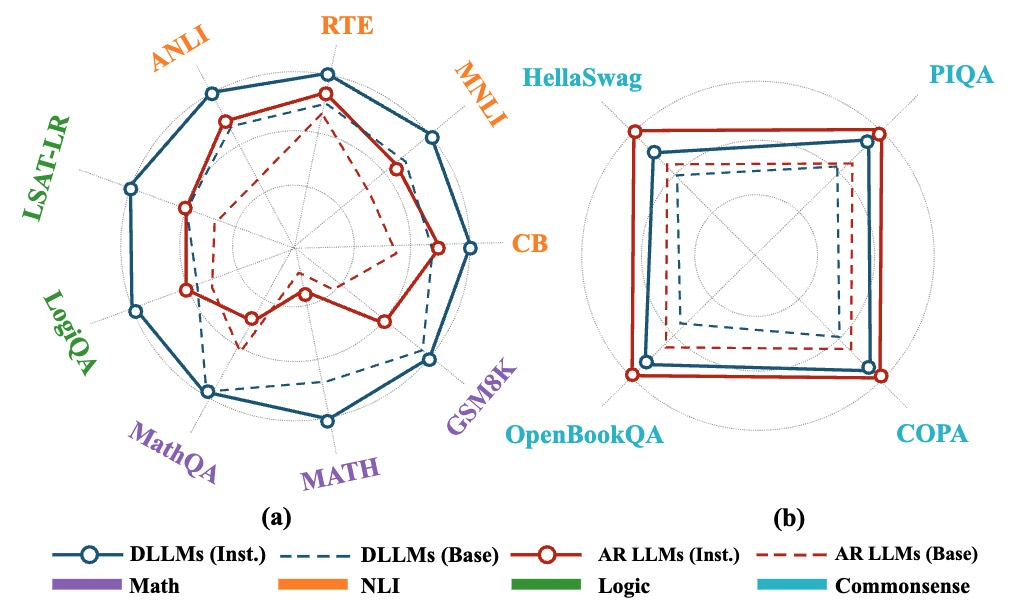
→ ExpandWe revisit LLM reasoning through two decoding paradigms, namely autoregressive large language models (AR LLMs) with next-token prediction, and diffusion-based large language models (DLLMs) with iterative denoising. Despite the growing interest in DLLMs, when each paradigm is preferable and how to elicit DLLM strengths remains unclear. We recast reasoning as trajectory formation, contrasting sequential commitment in AR LLMs with iterative refinement in DLLMs, and run a matched-scale study across mathematics, logic, natural-language inference, and commonsense reasoning. Empirically, DLLMs outperform AR LLMs on most reasoning benchmarks, especially those requiring global constraints and long-range coherence, whereas AR LLMs remain competitive on shorter, commonsense-oriented tasks. Further analyses show that DLLMs gradually correct early errors and enforce sequence-wide consistency, and robustness experiments reveal graceful degradation under prompt noise. The quantification of the accuracy and efficiency trade-off shows that DLLMs increase FLOPs and latency, yet compute matched comparisons preserve their advantage. Our results delineate regimes where diffusion decoding is advantageous and provide deployment guidance.
The Generative Crossroads: Diffusion or Autoregression for Language Modeling?
Xiang Zhang, Yiyang Liu, Runjia Zeng, et al.
EACL Findings Findings of the European Chapter of the Association for Computational Linguistics 2027
→ ExpandWe revisit LLM reasoning through two decoding paradigms, namely autoregressive large language models (AR LLMs) with next-token prediction, and diffusion-based large language models (DLLMs) with iterative denoising. Despite the growing interest in DLLMs, when each paradigm is preferable and how to elicit DLLM strengths remains unclear. We recast reasoning as trajectory formation, contrasting sequential commitment in AR LLMs with iterative refinement in DLLMs, and run a matched-scale study across mathematics, logic, natural-language inference, and commonsense reasoning. Empirically, DLLMs outperform AR LLMs on most reasoning benchmarks, especially those requiring global constraints and long-range coherence, whereas AR LLMs remain competitive on shorter, commonsense-oriented tasks. Further analyses show that DLLMs gradually correct early errors and enforce sequence-wide consistency, and robustness experiments reveal graceful degradation under prompt noise. The quantification of the accuracy and efficiency trade-off shows that DLLMs increase FLOPs and latency, yet compute matched comparisons preserve their advantage. Our results delineate regimes where diffusion decoding is advantageous and provide deployment guidance.
On the Token Value Inequality in Efficient Reasoning
Runjia Zeng, Hang Hua, Yiyang Liu, et al.
NeurIPS Conference on Neural Information Processing Systems 2026
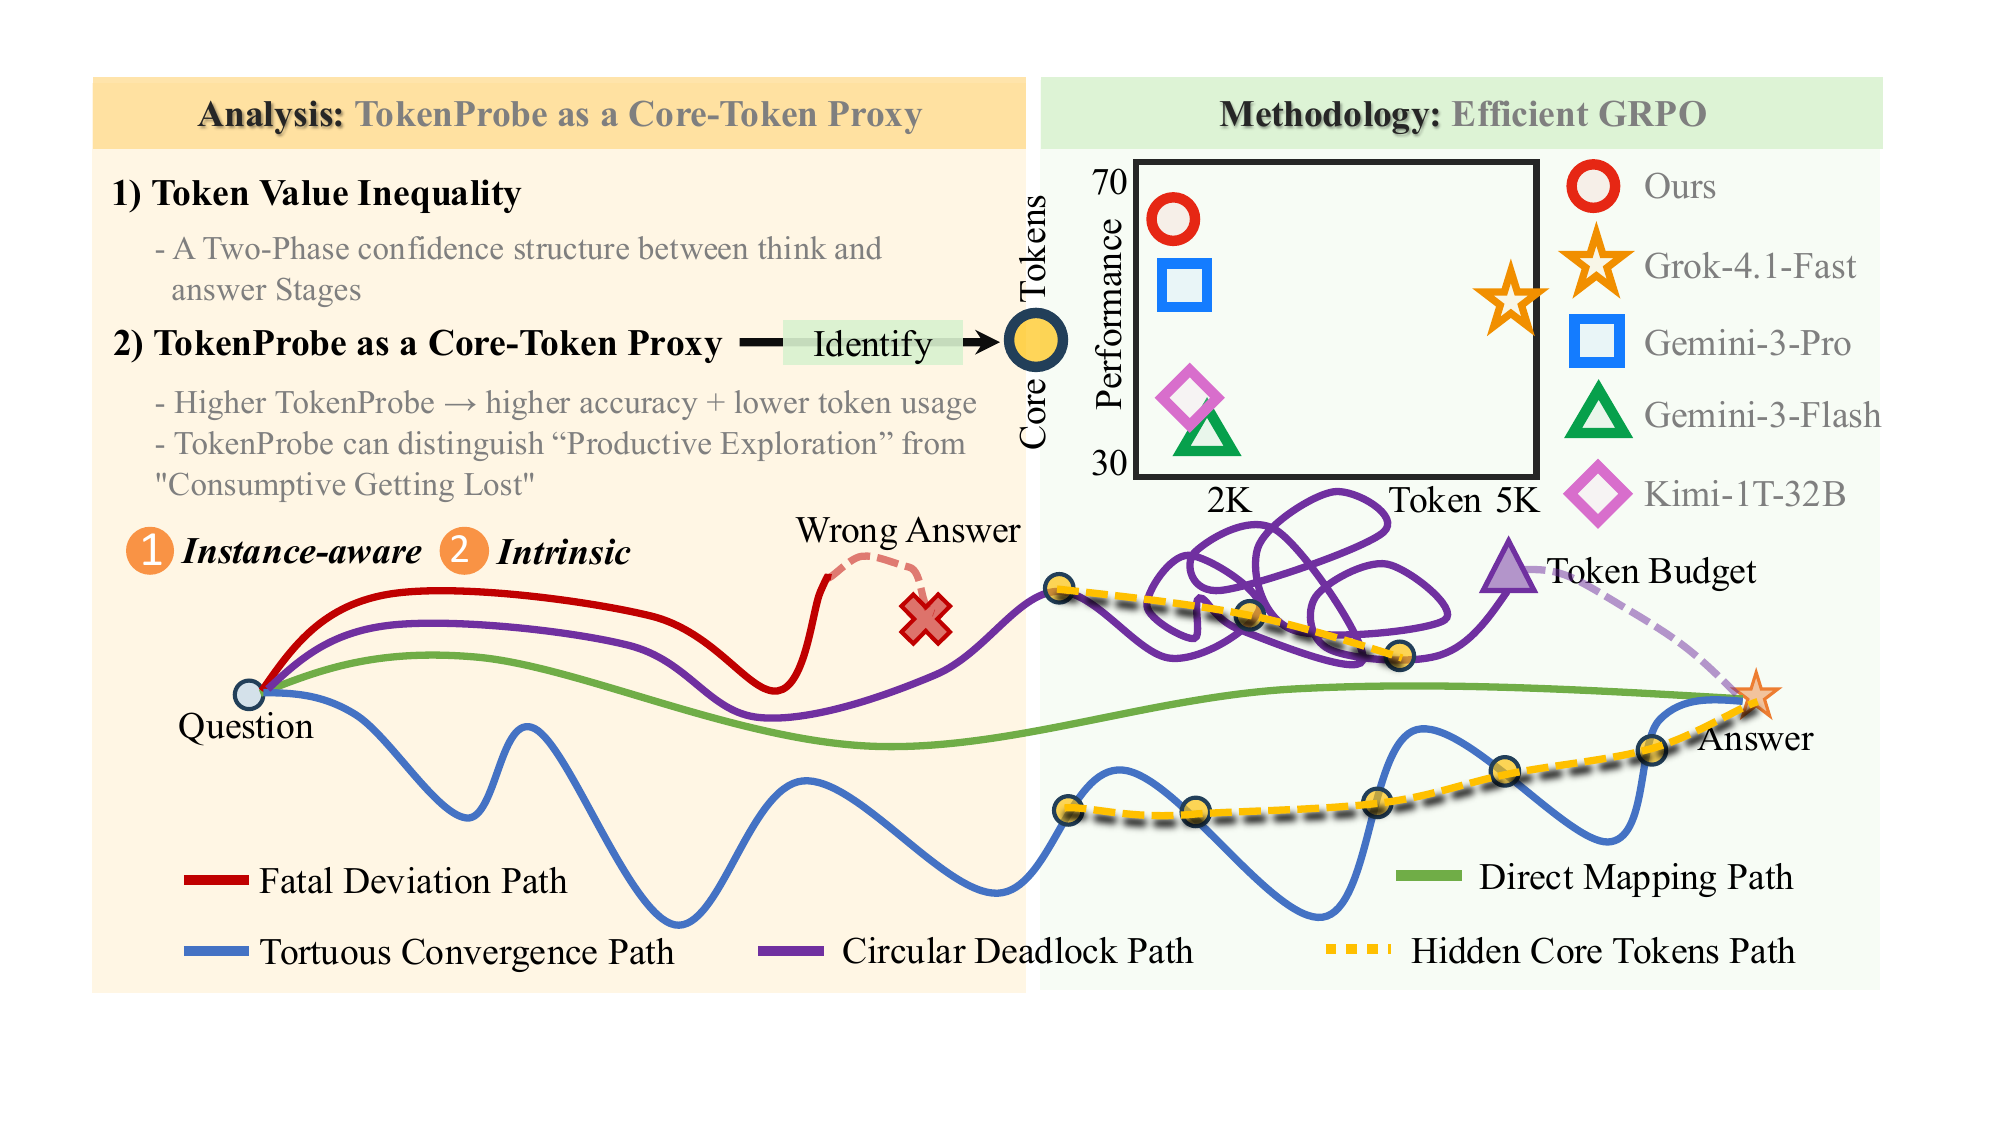
→ ExpandWe introduce TokenProbe, a diagnostic and optimization framework for efficient LLM reasoning based on token value inequality. Normalized token-level log probabilities distinguish core reasoning tokens from redundant exploration. An efficient GRPO objective selectively compresses redundant tokens, reducing token usage by 76% while preserving reasoning quality. Under matched reasoning-length budgets, TokenProbe can outperform strong flagship baselines such as Gemini-3.1-Pro.
On the Token Value Inequality in Efficient Reasoning
Runjia Zeng, Hang Hua, Yiyang Liu, et al.
NeurIPS Conference on Neural Information Processing Systems 2026
→ ExpandWe introduce TokenProbe, a diagnostic and optimization framework for efficient LLM reasoning based on token value inequality. Normalized token-level log probabilities distinguish core reasoning tokens from redundant exploration. An efficient GRPO objective selectively compresses redundant tokens, reducing token usage by 76% while preserving reasoning quality. Under matched reasoning-length budgets, TokenProbe can outperform strong flagship baselines such as Gemini-3.1-Pro.
Q-Bridge: Code Translation for Quantum Machine Learning via LLMs
Runjia Zeng, Priyabrata Senapati, Ruixiang Tang, et al.
arXiv 2026
[Paper📑] [Code💾] [Dataset📀] [Model📨]
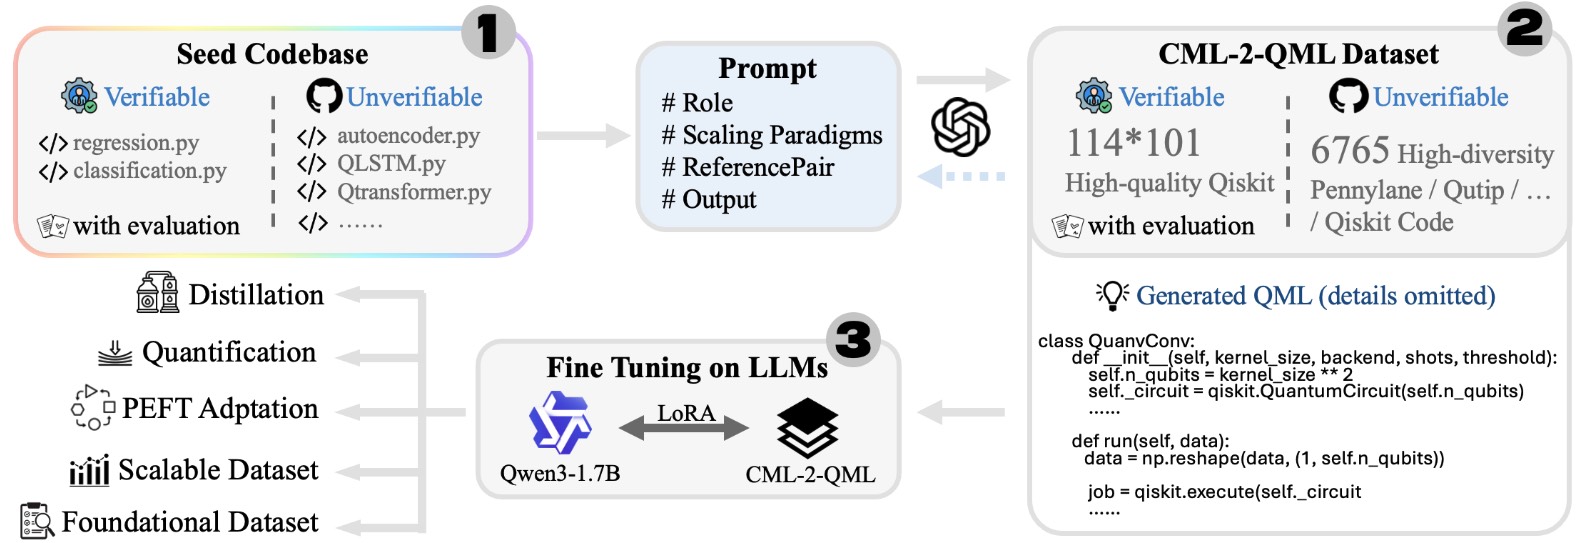
→ ExpandQ-Bridge is an LLM-guided framework for translating classical machine learning code into executable quantum machine learning variants, addressing the lack of standardized datasets and robust translation pipelines in this space. It builds a large-scale CML-2-QML dataset through a self-involving expansion process and fine-tunes the Q-Bridge model with supervised LoRA for scalable, memory-efficient training. Experiments and case studies show faithful, interpretable quantum code generation, supporting both deterministic correctness and creative architectural exploration.
Q-Bridge: Code Translation for Quantum Machine Learning via LLMs
Runjia Zeng, Priyabrata Senapati, Ruixiang Tang, et al.
arXiv 2026
[Paper📑] [Code💾] [Dataset📀] [Model📨]
→ ExpandQ-Bridge is an LLM-guided framework for translating classical machine learning code into executable quantum machine learning variants, addressing the lack of standardized datasets and robust translation pipelines in this space. It builds a large-scale CML-2-QML dataset through a self-involving expansion process and fine-tunes the Q-Bridge model with supervised LoRA for scalable, memory-efficient training. Experiments and case studies show faithful, interpretable quantum code generation, supporting both deterministic correctness and creative architectural exploration.
TokenSeek: Memory Efficient Fine Tuning via Instance-Aware Token Ditching
Runjia Zeng, Qifan Wang, Qiang Guan, et al.
ICLR International Conference on Learning Representations 2026
[Homepage💻] [Code💾] [Paper📑] [Poster🎇] [Media Coverage🎙️]
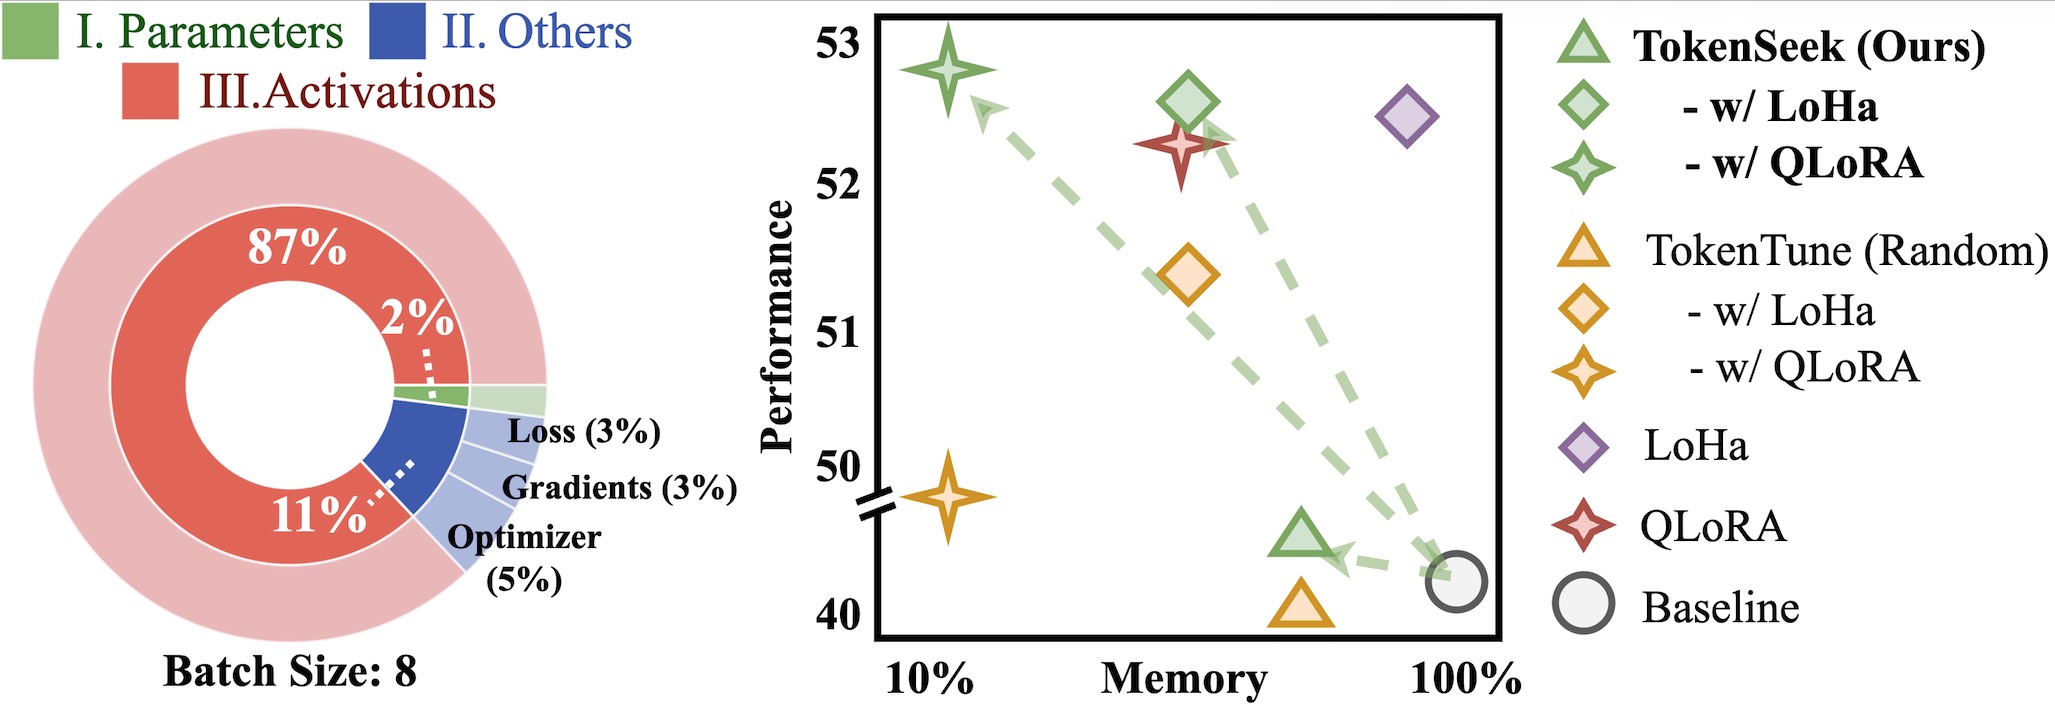
→ ExpandFine-tuning is a standard approach for adapting large language models to downstream tasks, but its efficiency is limited by high memory consumption, largely dominated by activations. We propose TokenSeek, a universal plugin for transformer-based models that performs instance-aware token seeking and ditching, achieving substantial memory savings (e.g., only 14.8% on Llama3.2 1B) while maintaining or even improving performance. Moreover, its interpretable token-seeking mechanism provides insights into why token efficiency can be improved.
TokenSeek: Memory Efficient Fine Tuning via Instance-Aware Token Ditching
Runjia Zeng, Qifan Wang, Qiang Guan, et al.
ICLR International Conference on Learning Representations 2026
[Homepage💻] [Code💾] [Paper📑] [Poster🎇] [Media Coverage🎙️]
→ ExpandFine-tuning is a standard approach for adapting large language models to downstream tasks, but its efficiency is limited by high memory consumption, largely dominated by activations. We propose TokenSeek, a universal plugin for transformer-based models that performs instance-aware token seeking and ditching, achieving substantial memory savings (e.g., only 14.8% on Llama3.2 1B) while maintaining or even improving performance. Moreover, its interpretable token-seeking mechanism provides insights into why token efficiency can be improved.
Probabilistic Token Alignment for Large Language Model Fusion
Runjia Zeng, James Chenhao Liang, Cheng Han, et al.
NeurIPS Conference on Neural Information Processing Systems 2025
[Homepage💻] [Code💾] [Paper📑] [Poster🎇]
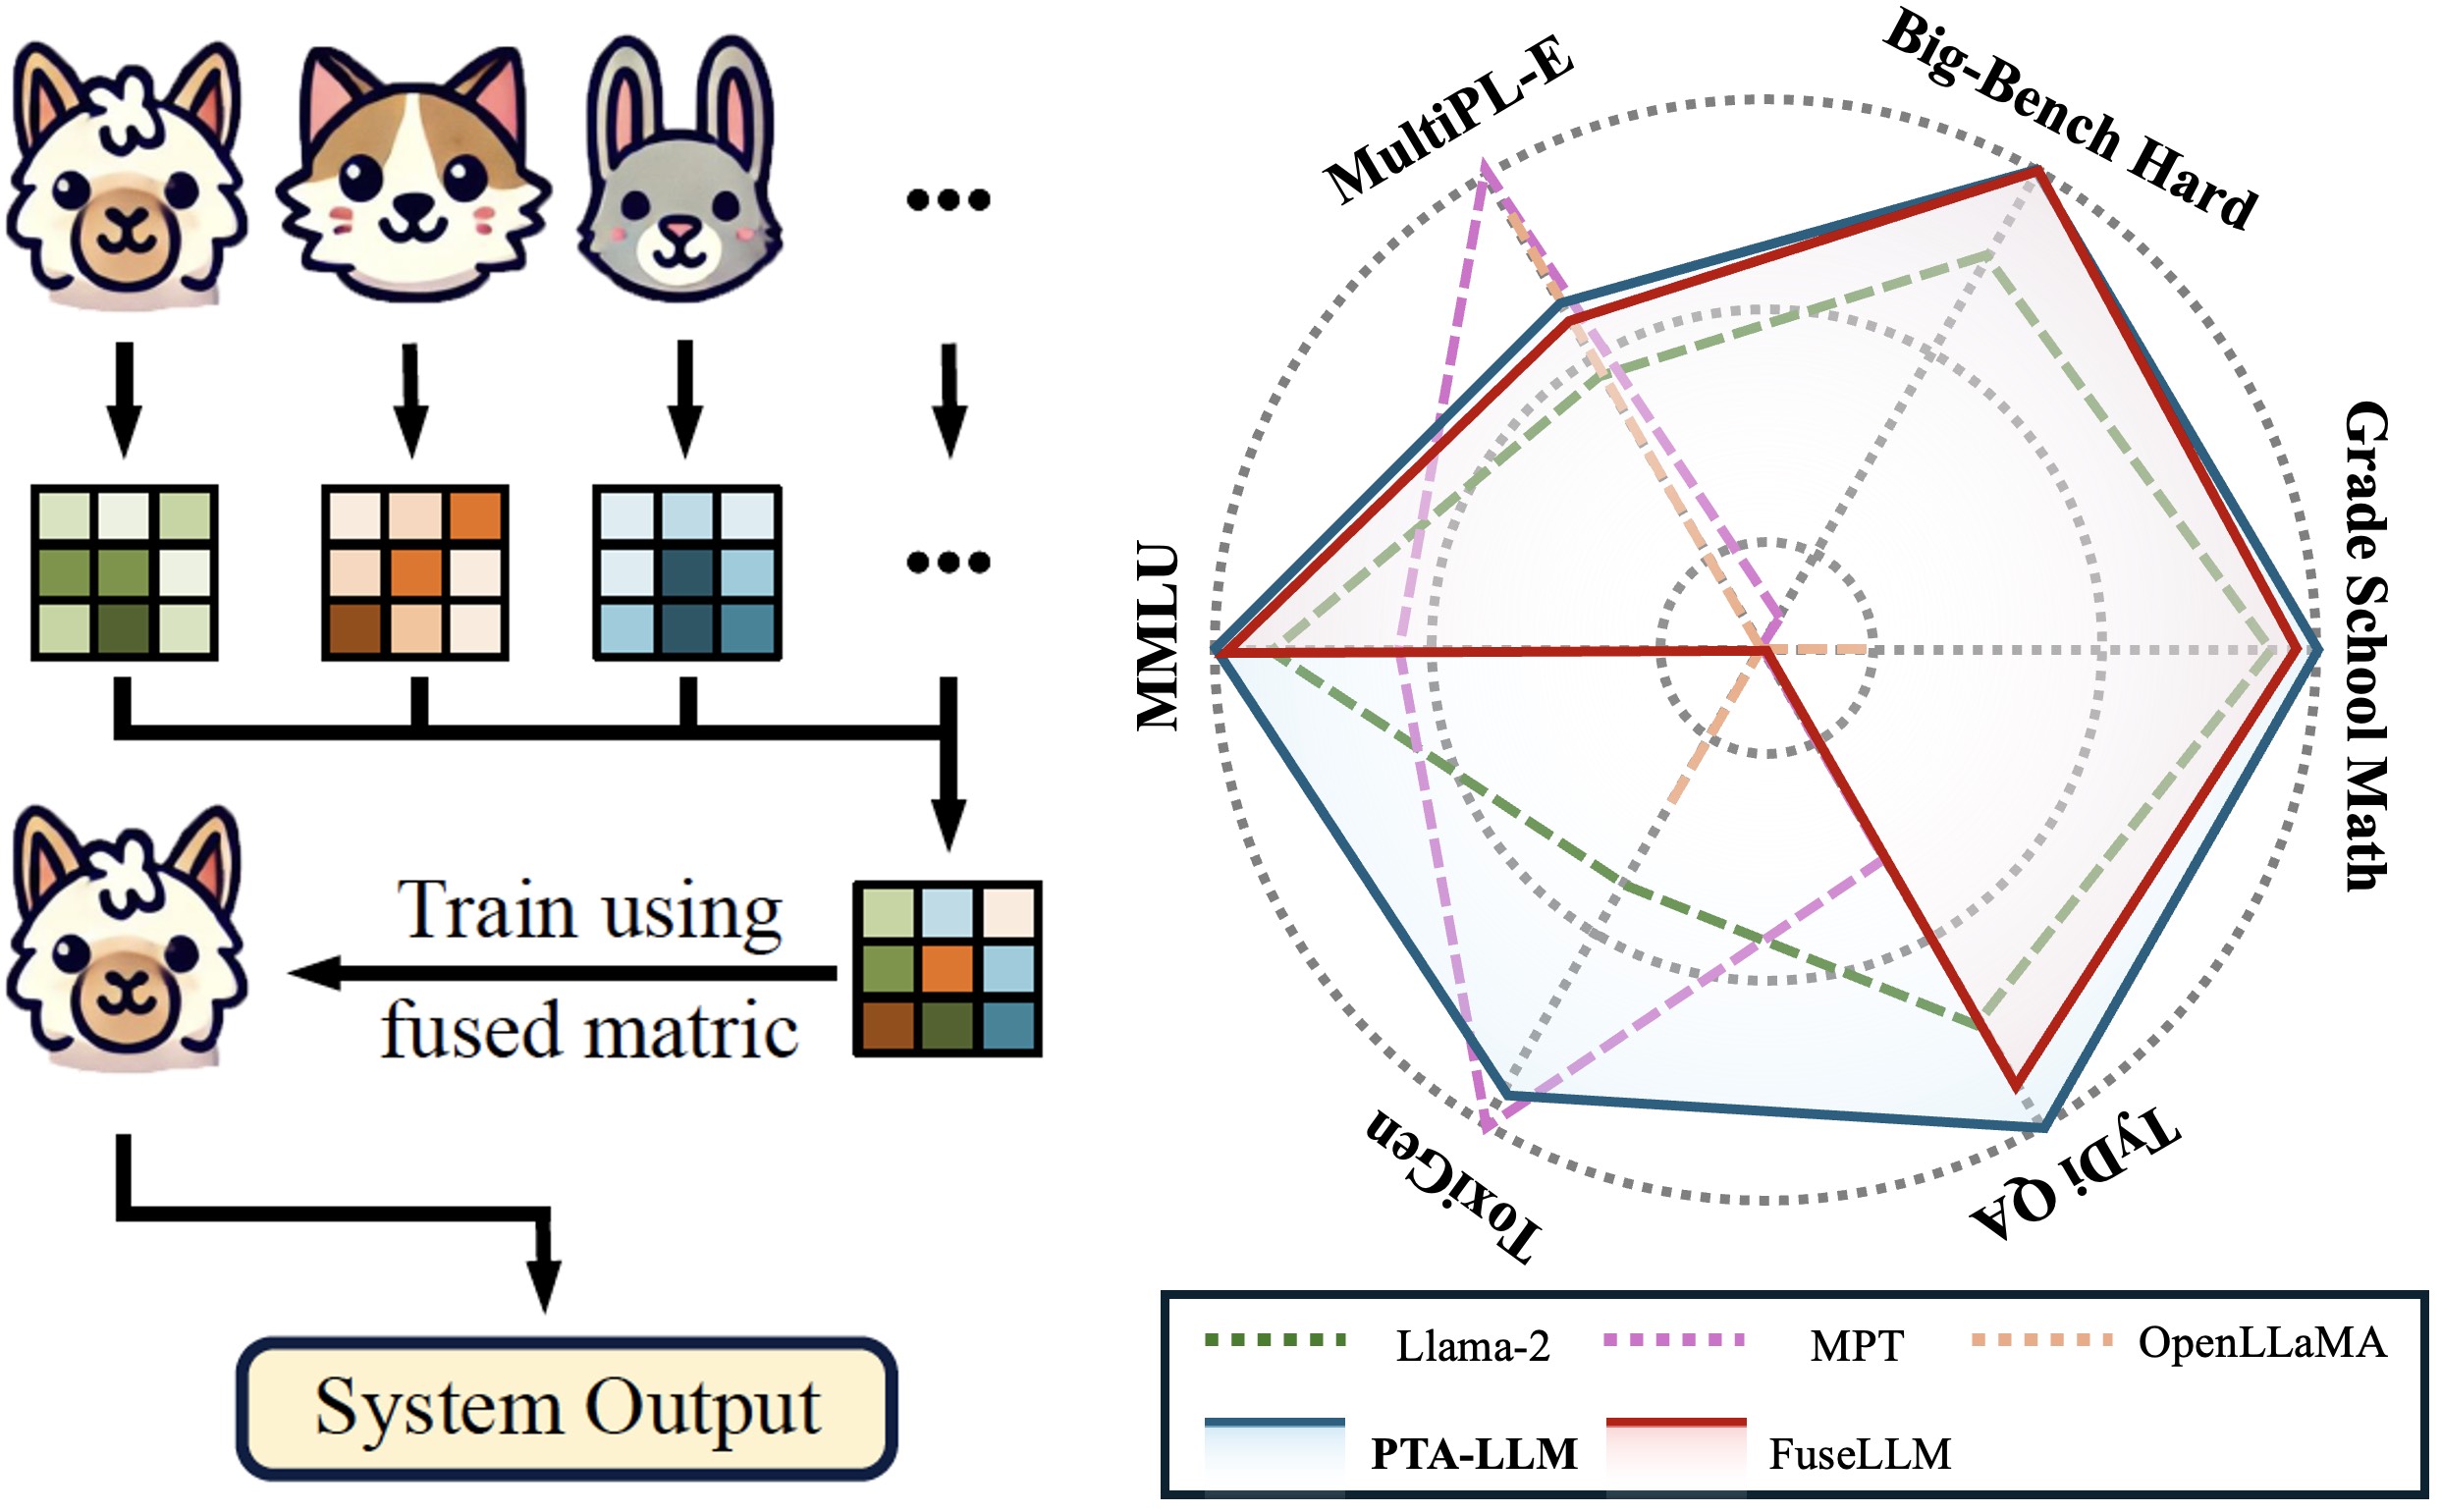
→ ExpandWe introduce Probabilistic Token Alignment (PTA) for large language model fusion, reformulating token alignment as an optimal transport problem. PTA enhances performance and generality through distribution-aware learning while offering interpretability from a distributional perspective, which provides deeper insights into token alignment.
Probabilistic Token Alignment for Large Language Model Fusion
Runjia Zeng, James Chenhao Liang, Cheng Han, et al.
NeurIPS Conference on Neural Information Processing Systems 2025
[Homepage💻] [Code💾] [Paper📑] [Poster🎇]
→ ExpandWe introduce Probabilistic Token Alignment (PTA) for large language model fusion, reformulating token alignment as an optimal transport problem. PTA enhances performance and generality through distribution-aware learning while offering interpretability from a distributional perspective, which provides deeper insights into token alignment.
MEPT: Mixture of Experts Prompt Tuning as a Manifold Mapper
Runjia Zeng, Guangyan Sun, Qifan Wang, et al.
EMNLP Conference on Empirical Methods in Natural Language Processing 2025
[Homepage💻] [Code💾] [Paper📑] [Poster🎇]
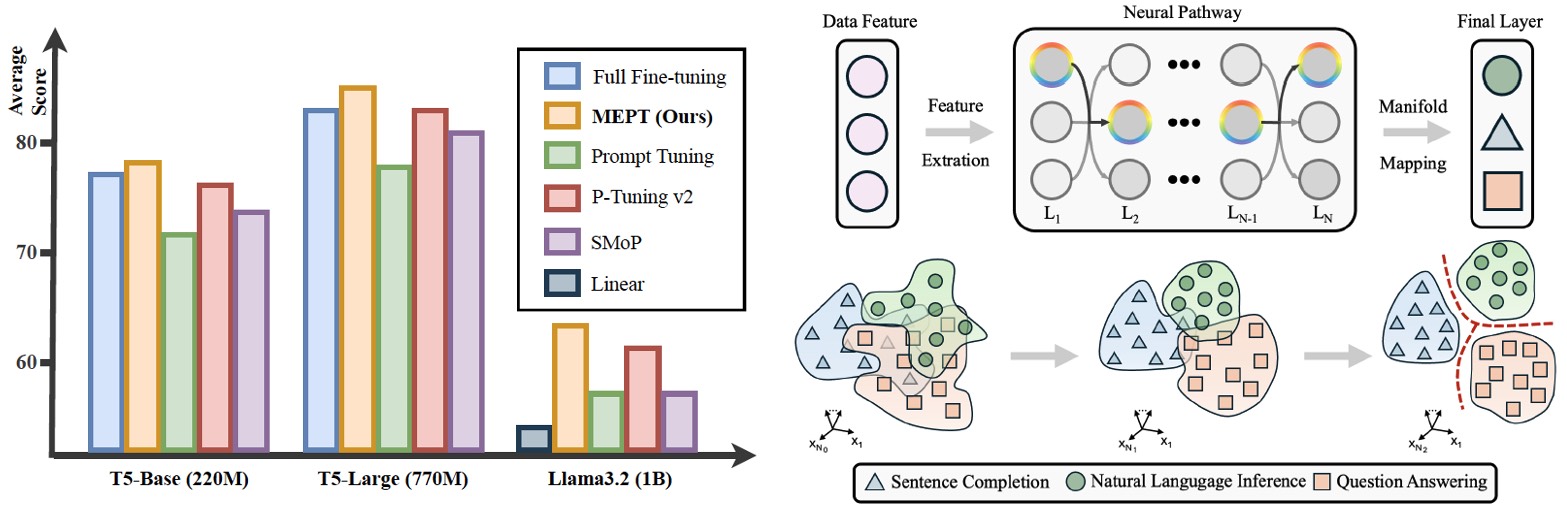
→ ExpandConsidering deep neural networks as manifold mappers, the pretrain-then-fine-tune paradigm is a two-stage process: pretrain builds a broad knowledge base, and fine-tune adjusts parameters to activate specific neural pathways aligning with the target manifold. The rigid parameter space constrain of prior prompt tuning methods limits dynamic pathway activation, making them less adaptable to diverse and evolving data. In this view, we propose Mixture of Expert Prompt Tuning (MEPT) that leverages multiple prompt experts to adaptively learn diverse and non-stationary data distributions.
MEPT: Mixture of Experts Prompt Tuning as a Manifold Mapper
Runjia Zeng, Guangyan Sun, Qifan Wang, et al.
EMNLP Conference on Empirical Methods in Natural Language Processing 2025
[Homepage💻] [Code💾] [Paper📑] [Poster🎇]
→ ExpandConsidering deep neural networks as manifold mappers, the pretrain-then-fine-tune paradigm is a two-stage process: pretrain builds a broad knowledge base, and fine-tune adjusts parameters to activate specific neural pathways aligning with the target manifold. The rigid parameter space constrain of prior prompt tuning methods limits dynamic pathway activation, making them less adaptable to diverse and evolving data. In this view, we propose Mixture of Expert Prompt Tuning (MEPT) that leverages multiple prompt experts to adaptively learn diverse and non-stationary data distributions.
Visual Fourier Prompt Tuning

Runjia Zeng, Cheng Han, Qifan Wang, et al.
NeurIPS Conference on Neural Information Processing Systems 2024
[Homepage💻] [Code💾] [Paper📑] [Slide📂] [Video🎞️] [Poster🎇] [Media Coverage🎙️]
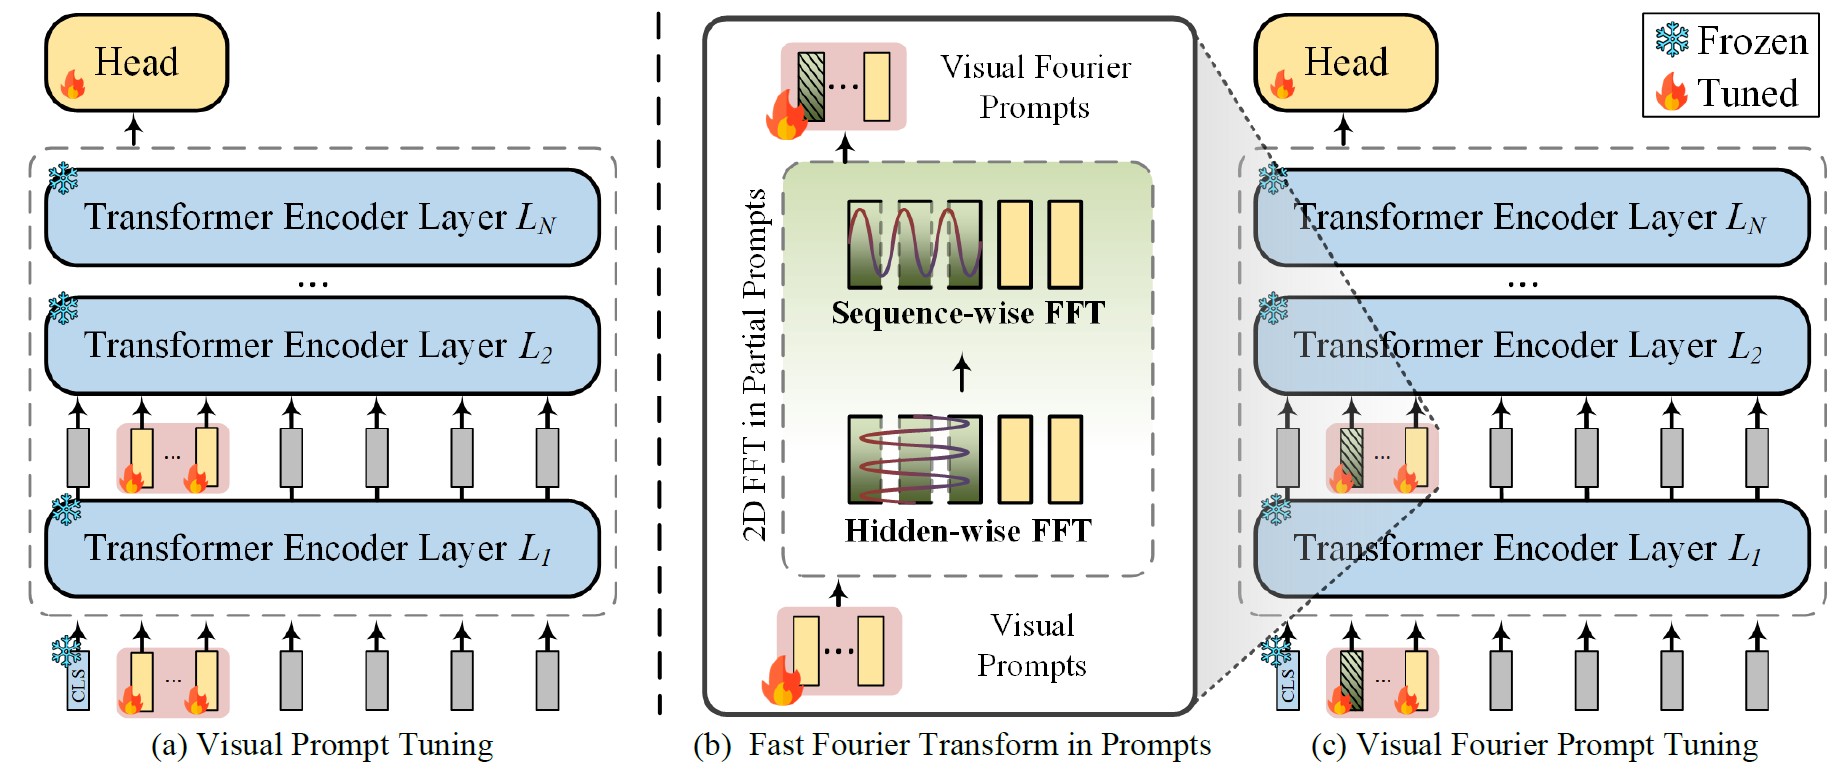
→ ExpandTo tackle performance drops caused by data differences between pretraining and finetuning, we propose Visual Fourier Prompt Tuning (VFPT), which leverages the Fast Fourier Transform to combine spatial and frequency domain information, achieving better results with fewer parameters.
Visual Fourier Prompt Tuning
Runjia Zeng, Cheng Han, Qifan Wang, et al.
NeurIPS Conference on Neural Information Processing Systems 2024
[Homepage💻] [Code💾] [Paper📑] [Slide📂] [Video🎞️] [Poster🎇] [Media Coverage🎙️]
→ ExpandTo tackle performance drops caused by data differences between pretraining and finetuning, we propose Visual Fourier Prompt Tuning (VFPT), which leverages the Fast Fourier Transform to combine spatial and frequency domain information, achieving better results with fewer parameters.